October 17, 2026
Dear [Hiring manager's name],
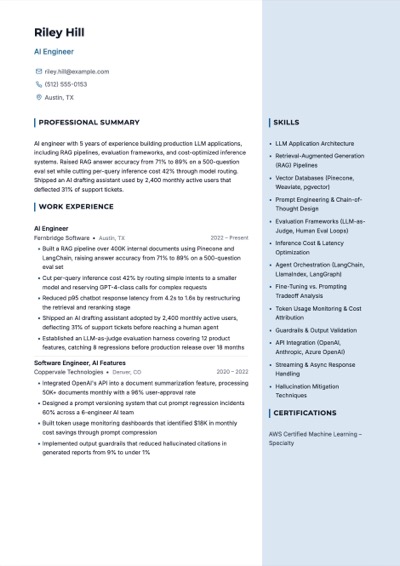
At Fernbridge Software I build the retrieval and evaluation systems behind our internal AI assistant, and I'm the engineer who gets asked first when an answer looks wrong. I'm applying for your AI Engineer opening because your team is clearly past the demo stage and into the harder problem of running LLM features against real production traffic.
My RAG pipeline over 400,000 internal documents took answer accuracy on our 500-question eval set from 71% to 89%, and routing simple intents to a smaller model before falling back to a larger one cut per-query inference cost 42% without moving that accuracy backward. The drafting assistant built on top of that pipeline now serves 2,400 people a month and deflects 31% of support tickets before they reach a human.
I hold the AWS Certified Machine Learning – Specialty credential, and I built the LLM-as-judge evaluation harness that now watches 12 product features and caught eight regressions before they shipped over the last year and a half. Earlier, at Coppervale Technologies, I got hallucinated citations in generated reports from 9% down to under 1% by adding output guardrails, so I plan for failure modes before a feature ships.
I'd welcome a conversation about how [Company name] is thinking about evaluation and cost as your AI features scale past the first few thousand users. I can walk through the eval harness and the routing setup in detail. Thank you for your time.
Sincerely,
Riley Hill